Using nftables to allow ingress traffic from internet to intranet resources

I recently heard about a case where someone wanted to allow an AWS EC2 instance on a public IP address to access a corporate intranet resource. Their solution was to run an HAProxy server on the corporate network that could proxy traffic from the AWS compute instance to the intranet server.

Whether or not accessing intranet resources from an external host is good idea or violates corporate policy I will leave aside for now, but I thought of 6 additional ways to accomplish the same objective.

What follow is one of those 6 ideas: using Network Address Translation (NAT) on the intermediary host via nftables. I have spent far more time with iptables than I have with nftables. But this seemed like a good opportunity to experiment.

The 3 servers for this example:

  1. The corporate intranet resource, intranet.osric.net or 192.0.2.43
  2. The NAT host, nat.osric.net or 198.51.100.200
  3. The AWS EC2 instance, ec2-203-0-113-155.compute-1.amazonaws.com or 203.0.113.155

The nat.osric.net server is running RHEL 10, although the commands should work on other systems using nftables.

I followed the steps provided by Configuring destination NAT using nftables on nat.osric.net:

sudo nft add table nat
sudo nft -- add chain nat prerouting { type nat hook prerouting priority -100 \; }
sudo nft add chain nat postrouting { type nat hook postrouting priority 100 \; }

The next commands needed the interface name, which I found using nmcli device status (ens5 in this case).

sudo nft add rule nat prerouting iifname ens5 tcp dport { 80, 443 } dnat to 192.0.2.43
sudo nft add rule nat postrouting oifname "ens5" snat to 198.51.100.200
echo "net.ipv4.ip_forward=1" | sudo tee /etc/sysctl.d/95-IPv4-forwarding.conf
sudo sysctl -p /etc/sysctl.d/95-IPv4-forwarding.conf

It worked! Well, with a couple caveats: an issue with the TLS certificate, and a wide-open NAT configuration.

The TLS certificate

From the EC2 instance:

$ curl https://198.51.100.200
curl: (60) SSL: no alternative certificate subject name matches target host name '198.51.100.200'
More details here: https://curl.se/docs/sslcerts.html

curl failed to verify the legitimacy of the server and therefore could not
establish a secure connection to it. To learn more about this situation and
how to fix it, please visit the web page mentioned above.

I could think of a few ways around this:

  • Add an entry to /etc/hosts on the client, i.e. on ec2-203-0-113-155.compute-1.amazonaws.com
  • Ignore the warning, e.g. curl --insecure https://198.51.100.200/
  • Add a subject alternative name (e.g. nat.osric.net) to the TLS cert for intranet.osric.net

The last method, adding a Subject Alternative Name (SAN) sounded like a pain, and also may not be feasible if you don’t manage the TLS certificate for that host. And I never like ignoring security warnings. But editing the /etc/hosts file was a simple solution that worked. Here’s the line I added to the EC2 instance (ec2-203-0-113-155.compute-1.amazonaws.com):

198.51.100.200   intranet.osric.net

After that, I was able to use curl https://intranet.osric.net/ to return content without errors or warnings.

The wide-open NAT

The configuration, as implemented, could allow anyone on the Internet to bypass the network security controls around intranet.osric.net. All they have to do is visit nat.osric.net (and maybe ignore some TLS warnings). This is terrible! Fortunately, we can use nftables to limit NAT to only specific inbound traffic.

How can I review what has already been added to nftables? Fortunately, Quick reference-nftables in 10 minutes was helpful here.

$ sudo nft list tables
table ip nat
$ sudo nft list chains
table ip nat {
        chain prerouting {
                type nat hook prerouting priority dstnat; policy accept;
        }
        chain postrouting {
                type nat hook postrouting priority srcnat; policy accept;
        }
}
$ sudo nft list ruleset
table ip nat {
        chain prerouting {
                type nat hook prerouting priority dstnat; policy accept;
                iifname "ens5" tcp dport { 80, 443 } dnat to 192.0.2.43
        }

        chain postrouting {
                type nat hook postrouting priority srcnat; policy accept;
                oifname "ens5" snat to 198.51.100.200
        }
}

In order to delete the dnat rule, I needed its handle. To get this, I used the -a flag:

$ sudo nft -a list ruleset
table ip nat { # handle 1
        chain prerouting { # handle 1
                type nat hook prerouting priority dstnat; policy accept;
                iifname "ens5" tcp dport { 80, 443 } dnat to 192.0.2.43 # handle 8
        }

        chain postrouting { # handle 2
                type nat hook postrouting priority srcnat; policy accept;
                oifname "ens5" snat to 198.51.100.200 # handle 9
        }
}

I deleted handle 8:

sudo nft delete rule nat prerouting "handle 8"

And added a new prerouting rule:

sudo nft add rule nat prerouting iifname ens5 ip saddr 203.0.113.155 tcp dport { 80, 443 } dnat to 192.0.2.43

That provides NAT for only the EC2 instance at 203.0.113.155.

The thing that I like about this solution is that it requires no new software. It uses the networking functionality that is already present on the host. However, unless you take additional steps, there is virtually no logging. nftables can log messages to syslog for packets that match the DNAT rule, but even that is very different than the level of logging that a proxy server would provide.

References:

During some initial testing, I was using another EC2 instance as the NAT server and it did not work immediately. That’s because the EC2 instance was not aware of its own public IPv4 address, it was only aware of its private IPv4 address: 172.31.15.224. Removing the SNAT rule for the public IP address and adding a new SNAT rule for 172.31.15.224 solved that.
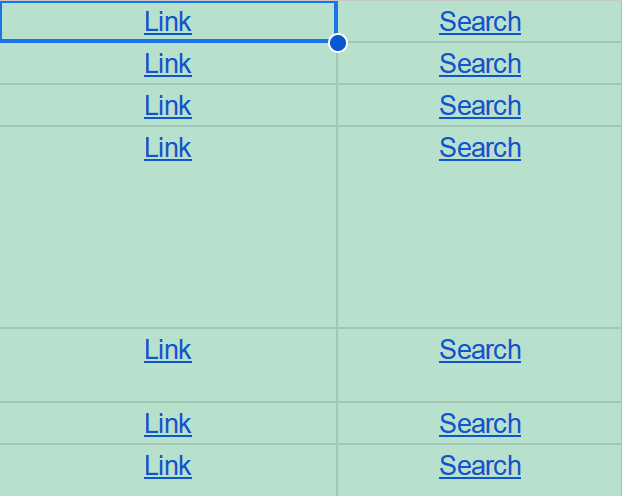
Extracting links from Google Sheets

I was working with a shared Google Sheet at work and ran into this:

An excerpt of a Google Sheet. Each row contains a cell with a hyperlink labeled Link
An excerpt of a Google Sheet. Each row contains a cell with a hyperlink labeled Link, but the actual URL is not displayed.

I get it, URLs can be long and messy. We want narrow columns that look clean, not cluttered. But I wanted to analyze the URLs and search for certain content and patterns, which were hidden from me behind the link text.

How can I extract all the URLs?
Continue reading Extracting links from Google Sheets

Minor improvements to legacy Perl code

We’re always working with code we didn’t write. You’ll spend far more time looking at code you didn’t write (or don’t remember writing) than you will spend writing new code.

Today I looked at an example Perl script that used 45 lines of code to pull the company associated with an OUI (Organizationally Unique Identifier) from a text file, given a MAC address.

I thought I could do slightly better.

find_mac_co.sh:

#!/bin/sh
OUI=$(echo "$1" | sed 's/[^A-Fa-f0-9]//g' | cut -c1-6)
awk -F "\t" -v IGNORECASE=1 -v OUI="$OUI" '$0 ~ OUI { print $3 }' ouidb.tsv
exit 0

Example run:

$ sh find_mac_co.sh 7c:ab:60:ff:ff:ff
Apple, Inc.

There’s probably a way to make the Perl version shorter too. I’m more familiar with bash and shell commands.

The biggest problem with this script is that it relies on an up-to-date list of OUIs. An even better way is to query an API:

find_mac_co_api.sh

#!/bin/sh
MACADDRESS="$1"
curl "https://api.maclookup.app/v2/macs/$MACADDRESS/company/name"
exit 0

Example run:

$ sh find_mac_co_api.sh 7c:ab:60:ff:ff:ff
Apple, Inc.

Renaming multiple files: replacing or truncating varied file extensions

In the previous post, I ran into an issue where Wget saved files to disk verbatim, including query strings/parameters. The files on disk ended up looking like this:

  • wp-includes/js/comment-reply.min.js?ver=6.4.2
  • wp-includes/js/jquery/jquery-migrate.min.js?ver=3.4.1
  • wp-includes/js/jquery/jquery.min.js?ver=3.7.1
  • wp-includes/css/dist/block-library/style.min.css?ver=6.4.2

I wanted to find a way to rename all these files, and truncate the filename after and including the question mark. As an example, to convert jquery.min.js?ver=3.7.1 to jquery.min.js.

Continue reading Renaming multiple files: replacing or truncating varied file extensions

3 ways to remove blank lines from a file

There are certainly more than 3 ways to do this. Typically I’ve always used sed to do this, but here’s my method using sed and two other methods using tr and awk:

sed:

sed '/^$/d' file_with_blank_lines

tr:

tr -s '\n' <file_with_blank_lines

awk:

awk '{ if ($0) print $0 }' file_with_blank_lines

If you have other favorite ways, leave a note in the comments!

Size of data in bytes

This was prompted by an error I was running into with the AWS s3 service: I needed to tell the transfer utility the size of the data, in bytes, when transferring large files.

In this case I am looking at files of characters. Some of these methods should work equally well for binary files, and others don’t. In the following examples, I’ll use the full text of Moby-Dick from Project Gutenberg, 2701-0.txt, as the target file. I retrieved the file using the following command:

curl -O http://www.gutenberg.org/files/2701/2701-0.txt

A couple commands to get size in bytes immediately came to mind: ls, stat, and wc.

$ ls -l 2701-0.txt | cut -d' ' -f5
1276201

$ stat --format %s 2701-0.txt 
1276201

$ wc -c 2701-0.txt | cut -d' ' -f1
1276201

All those options work. But what if the input isn’t a file on disk, and instead is an input stream? This is to demonstrate counting the bytes in a character stream coming from any source, so forgive the “useless use of cat”:

$ cat 2701-0.txt | wc -c
1276201

$ cat 2701-0.txt | cksum | cut -d' ' -f2
1276201

$ cat 2701-0.txt | dd of=/dev/null
2492+1 records in
2492+1 records out
1276201 bytes (1.3 MB, 1.2 MiB) copied, 0.00997434 s, 128 MB/s

The output from dd above is not the simplest thing to parse. It’s multi-line and sent to stderr, so I redirected it to stdout and grepped for “bytes”:

$ cat 2701-0.txt | dd of=/dev/null 2>&1 | grep 'bytes' | cut -d' ' -f1
1276201

There are at least 5 methods to find the size of a file using common command-line tools:

  • ls
  • stat
  • wc
  • cksum
  • dd

Know of others? Leave a comment below.

Running VMs? Delete wireless packages!

A best practice for system configuration is to remove any unneeded software. It’s sometimes difficult to know exactly what is needed and what isn’t, but CentOS 7 minimal and CentOS 8 minimal both install a number of packages related to wireless networking. If you’re running a server or a VM there’s almost never a need for these to be present.

To identify packages, I used yum search (substitute dnf for yum on CentOS 8):

yum search wireless

I used the same command a redirected the output to a file:

yum search wireless >wireless_packages

To get just the package names and convert it to a space-separated list, I used grep, cut, and paste:

grep -v Summary wireless_packages | cut -d. -f1 | paste -d' ' -s

You can remove them with the following command:

sudo yum remove iw iwl6000-firmware crda iwl100-firmware iwl1000-firmware iwl3945-firmware iwl4965-firmware iwl5000-firmware iwl5150-firmware iwl105-firmware iwl135-firmware iwl3160-firmware iwl6000g2a-firmware iwl6000g2b-firmware iwl6050-firmware iwl2000-firmware iwl2030-firmware iwl7260-firmware

iw and crda were not installed, so were ignored. The rest were removed.

This may seem trivial, but it frees up some disk space (~100MB) and it means that these packages won’t need to be updated in the future. Getting notifications from your monitoring systems or vulnerability management systems about updates or security updates to unused and unnecessary packages should be avoided.

Combining pcap (packet capture) files

Motivation: I wanted to combine 2 or more packet capture, or pcap, files in order to create an example:

  • One that contains just malicious (or simulated malicious) network traffic
  • Another contains legitimate, non-malicious network traffic

Many example packet capture files focus either specifically on malware, exploits, C2 traffic, etc. (like Security Onion’s list of PCAPs for Testing) or on examples of legitimate traffic (like Wireshark’s Sample Captures). I wanted to create an example that would interweave such sources and intersperse malicious and legitimate traffic, as they would typically occur concurrently.

In addition to tcpdump, there are three CLI tools provided by Wireshark that I used to help accomplish this:

  • capinfos – provides high-level data about a packet capture file
  • mergecap – combines 2 or more packet capture files
  • editcap – modified packet details, such as timestamps, in a packet capture file

Continue reading Combining pcap (packet capture) files

curl basic auth using base64 encoded credentials

I was trying to access password-protected files via HTTPS using curl. The site required basic auth. For a demo, I created this example:

https://osric.com/chris/demo/admin/
Username: admin
Password: 123456

It’s trivial to access this interactively via curl:

$ curl -u admin https://osric.com/chris/demo/admin/
Enter host password for user 'admin':

Or programmatically by providing the credentials in the URL:

$ curl https://admin:123456@osric.com/chris/demo/admin/

Or by providing a base64-encoded username:password pair in an Authorization header:

$ curl -H "Authorization: Basic $(echo -n admin:123456 | base64)" https://osric.com/chris/demo/admin/

(Note that echo includes a trailing newline character by default, which we do not want to include in the base64-encoded value. Specify the -n flag to echo to eliminate the trailing newline.)

But I was manipulating files with a Bash script that was being stored in a Git repository, and I didn’t want to store the credentials in the repository. So I stored the credentials in a separate file:

$ echo -n 'admin:123456' > ~/admin-credentials
$ chmod 0600 ~/admin-credentials

Now I can read the credentials from the file:

$ curl -H "Authorization: Basic $(cat admin-credentials | base64)" https://osric.com/chris/demo/admin/

I ran into a problem when I tried to update the credentials file with vi (or vim). Vi automatically inserts an end-of-line (EOL) character, which is not apparent to the user. The base64-encoded value includes the EOL character, and therefore the above command would supply invalid credentials.

To eliminate this in vi, use the following vi commands:

:set binary
:set noeol

Alternately, just overwrite the file with the updated credentials:

$ echo -n 'admin:123456' > ~/admin-credentials

Make a CVS project read-only

In the previous post, Converting a CVS project to a Git repository, I describe using cvs2git to convert a CVS project to a git repository. After I made the conversion, I wanted to make the CVS project read-only.

There’s probably no reason to keep the CVS project around (the history is in the git repo, and I have backups of the CVS project), but it felt like the right thing to do. The blog post Read-only CVS access for only certain projects was extremely helpful to accomplish this.

The key component is the CVSROOT/commitinfo file within your CVS repository. Like any other project in CVS, you need to check this out to make changes:

cvs co CVSROOT
cd CVSROOT && vi commitinfo

You specify a regular expression and a script to run before committing data to a project matching that regular expression. If the script exits with a non-zero exit code (indicating an error), the commit is aborted. For initial testing, I used false (or /bin/false) for the script component, which does nothing and returns an exit code of 1.

I had some problems with this, in part because I was not sure what the project string would look like. I tried a few things:

  • ^/testrepo/.* false (didn’t work)
  • ^testrepo/.* false didn’t work
  • ^t.* false worked, but would match other projects as well

Eventually I switched to using the read-only-project.sh example from the aforementioned blog post, which printed out the values of the project path and the filenames to be committed.

From there I could see that the project path:

  • Does not include an initial slash
  • Does not include a trailing slash
  • May include additional slashes if the project contains subdirectories

The same script suggests including the following in commitinfo:

^projectname/.* /path/to/script "%p" %s

That regular expression does not work — it would match a file at projectname/subdir1/file1 but not projectname/file1.

And what do the “%p” and %s mean? From C.3.4 Commitinfo:

Currently, if no format strings are specified, a default string of ` %r/%p %{s}’ will be appended to the command line template before replacement is performed, but this feature is deprecated.

I found another document, C.3.1 The common syntax, which describes the format strings.

  • p – the name of the directory being operated on within the repository.
  • {s} – the file name(s), in curly braces because it is a list

The same page includes a sample regular expression that solves the problem I was having:

^module\(/\|$\)

Finally, here is what I added to CVSROOT/commitinfo:

^testrepo\(/\|$\) /usr/local/script/read-only-project.sh

Note that this script needs to exist on the same machine as the CVS repository (which may or may not be the same machine as your checked-out copy).